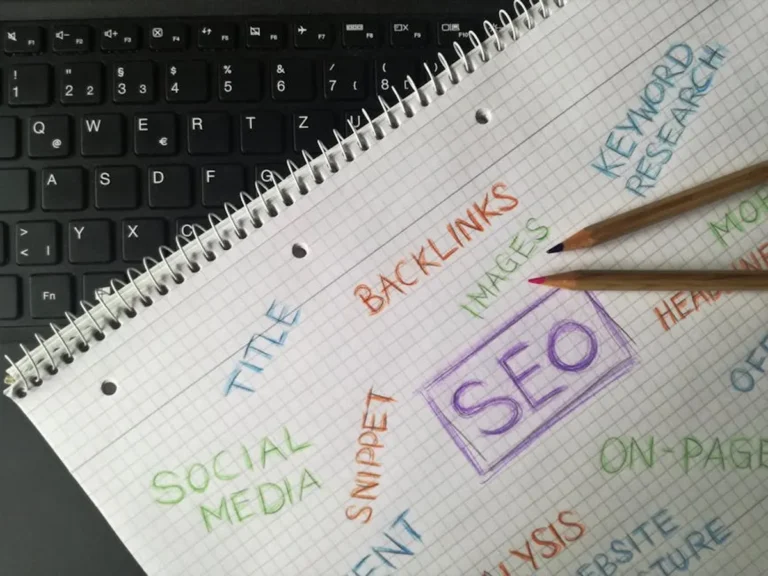
Effective website crawlability and indexing are not merely technical checkboxes; they are foundational to organic search visibility and, consequently, to a site's ability to generate traffic, leads, and revenue. Without efficient crawling, search engines cannot discover new or updated content. Without proper indexing, even discovered content remains invisible in search results. This directly impacts your organic reach and competitive standing. Understanding and actively managing these processes ensures that your digital assets are not just published, but are also discoverable and rankable, translating directly into business opportunities.
Understanding Crawl Budget and Its Impact
Crawl budget refers to the number of pages and the frequency with which a search engine bot will crawl a website within a given timeframe. It's not an unlimited resource; larger or more frequently updated sites generally receive more, but inefficiencies can waste this budget on low-value pages, leaving critical content undiscovered. Search engines prioritize crawling based on factors like site authority, update frequency, and perceived value of content. Optimizing crawl budget means directing bots to the most important content first, ensuring timely indexing of pages that drive business value.
Impact on visibility: Wasted crawl budget can delay the indexing of new products, services, or articles, causing missed opportunities for early ranking and traffic capture. For large e-commerce sites or news publishers, this can mean significant revenue loss.
Technical Foundations for Indexing Success
A robust technical infrastructure is paramount for efficient crawling and indexing. These elements guide search engine bots, prevent common issues, and ensure content is accessible.
Robots.txt and XML Sitemaps
The robots.txt file serves as a directive for search engine crawlers, instructing them which parts of a site they are permitted or restricted from accessing. While it doesn't prevent indexing if a page is linked elsewhere, it controls crawling. Misconfigurations can inadvertently block critical sections of a site, rendering them invisible to search engines. Conversely, strategic use can conserve crawl budget by preventing bots from wasting time on irrelevant or duplicate content, such as admin pages or faceted navigation filters.
XML sitemaps, on the other hand, act as a roadmap, providing search engines with a comprehensive list of all important pages on your site. They are particularly valuable for large sites, new sites with few external links, or sites with complex architectures. A well-maintained sitemap helps search engines discover all relevant URLs, including those that might not be easily found through internal linking alone, thus facilitating faster and more complete indexing.
Canonicalization and Pagination
Duplicate content, whether due to URL variations (e.g., www.example.com vs. example.com, or URLs with tracking parameters), pagination, or content syndication, can dilute link equity and confuse search engines about which version to index. Canonical tags (<link rel="canonical" href="...">) specify the preferred URL for a set of similar pages, consolidating ranking signals to a single version. This prevents search engines from splitting ranking authority across multiple URLs and ensures that the intended page receives full credit.
For paginated series (e.g., product categories, blog archives), using rel="canonical" to point to a "view all" page (if applicable) or ensuring each page in the series is self-canonicalized helps manage crawl flow and indexing without creating duplicate content issues. Avoid using noindex on paginated pages unless absolutely necessary, as this can prevent search engines from discovering content deeper within the series.
Site Speed and Server Response
Slow site speed directly impacts crawl efficiency and user experience. Search engine bots have a limited time they will spend on a site; if pages load slowly, they may crawl fewer pages or abandon the crawl altogether. A fast server response time (TTFB – Time To First Byte) is critical, as it signals to crawlers that the site is healthy and responsive. Optimizing image sizes, leveraging browser caching, minifying CSS/JavaScript, and using a Content Delivery Network (CDN) all contribute to improved load times, which in turn supports more thorough crawling and a better chance of indexing.
Pro Tip: Regularly audit your
robots.txtfile, especially after site redesigns or migrations. A single misplacedDisallow: /directive can de-index your entire site, leading to catastrophic organic traffic loss. Verify its contents using a robots.txt tester tool to ensure it only blocks intended sections.
Optimizing Content for Discoverability
Beyond technical configurations, the content itself and its presentation play a crucial role in how effectively it is crawled and indexed.
Internal Linking Structure
A well-planned internal linking structure guides search engine crawlers through your site, helping them discover new pages and understand the hierarchical relationship between content. Strong internal links from authoritative pages pass PageRank and relevance signals to target pages, indicating their importance. Orphaned pages—those without any internal links pointing to them—are difficult for crawlers to find and index, regardless of their quality. Strategic internal linking ensures that all valuable content is within reach of search engine bots, distributing link equity effectively across the site.
Content Quality and Uniqueness
Search engines prioritize high-quality, unique, and valuable content that genuinely addresses user intent. Pages with thin content, boilerplate text, or content duplicated from other sources are less likely to be crawled frequently or indexed prominently. Focus on creating comprehensive, authoritative, and engaging content that provides real value to your audience. This not only encourages better user engagement but also signals to search engines that your content is worth crawling and indexing, ultimately contributing to higher rankings.
Monitoring and Troubleshooting Indexing Issues
Proactive monitoring is essential to identify and resolve crawl and indexing problems before they significantly impact organic performance.
Search Console Insights
Google Search Console (GSC) is an indispensable tool for monitoring how Google crawls and indexes your site. The 'Index Coverage' report provides a detailed overview of indexed pages, pages with errors, and excluded pages, along with reasons for exclusion. The 'Crawl Stats' report offers insights into crawl activity, including the number of pages crawled daily, download time, and response status. Regularly reviewing these reports helps identify issues like server errors, soft 404s, or pages blocked by robots.txt that hinder indexing. To further diagnose these and other potential issues, utilizing the right SEO audit tools can provide a comprehensive overview of your site's health.
Log File Analysis
Analyzing server log files provides direct insight into how search engine bots interact with your site. These logs record every request made to your server, including those from crawlers. By examining log data, you can see which pages are being crawled, how frequently, the response codes received by crawlers, and identify crawl patterns. This allows you to verify if important pages are being visited as expected, pinpoint areas where crawl budget is being wasted, or detect issues like excessive 404s that might signal broken links or missing content.
Strategic Actions for Sustained Visibility
Maintaining optimal crawlability and indexing requires ongoing effort and a strategic approach.
- Regular Technical Audits: Schedule periodic technical SEO audits to identify and rectify issues like broken links, redirect chains, canonicalization errors, and
robots.txtmisconfigurations. - Content Pruning and Refreshing: Remove or update outdated, low-quality, or duplicate content that consumes crawl budget without providing value. Focus on consolidating similar content to create more authoritative resources.
- Prioritize Mobile-First Indexing: Ensure your mobile site (or responsive design) is fully crawlable and indexable, as Google primarily uses the mobile version of content for indexing and ranking.
- Monitor Core Web Vitals: Improve page experience signals (LCP, FID, CLS) as these can indirectly influence crawl frequency and indexing priority.
- Submit Sitemaps Regularly: Ensure your XML sitemaps are up-to-date and submitted to search engines, especially after major site changes or content additions.
Frequently Asked Questions
How often should I check my site's crawl and indexing status?
For active sites with frequent content updates, a weekly review of Google Search Console's Index Coverage and Crawl Stats reports is advisable. For smaller, less dynamic sites, a monthly check can suffice, but any significant site changes warrant immediate re-evaluation.
What is the most common reason pages don't get indexed?
The most common reasons include being blocked by robots.txt, having a noindex tag, being considered duplicate content and canonicalized away, or being perceived as low-quality or thin content by search engines.
Does site speed directly affect indexing?
While site speed doesn't directly prevent indexing, extremely slow sites can lead to reduced crawl rates. Crawlers may spend less time on your site, resulting in fewer pages being discovered and indexed, especially for large sites. It also impacts user experience, which is an indirect ranking factor.
Can internal linking really impact indexing?
Yes, a robust internal linking structure is crucial. It helps search engine bots discover new pages, understand the site's architecture, and pass link equity. Pages that are not internally linked (orphaned pages) are significantly harder for crawlers to find and index.